Welcome to curated list of handpicked free online resources related to IT, cloud, Big Data, programming languages, Devops. Fresh news and community maintained list of links updated daily. Like what you see? [ Join our newsletter ]

A cloud-like on-prem load balancer for Kubernetes?

Categories

Tags cloud-and-infrastructure devops-and-ci-cd

Everyone knows that using a Kubernetes Load Balancer is a challenge. Back in the day when I was responsible for network operations, the load balancer management was under my team’s responsibility too. By Alex Saroyan.

Public cloud providers offer a great deal of convenience by automatically provisioning and configuring the services needed by the application.

All major public cloud providers offer on-demand load balancer services that you use for exposing your Kubernetes applications to the public Internet. Or you are using an Ingress controller and your Ingress controller is using the on-demand load balancer for exposing it’s public TCP port towards the Internet.

In the article you will learn:

  • What user experience are cloud practitioners expecting from Layer-4 load balancers?
  • How can we get this cloud-like experience in a private cloud, on-prem?
  • Where is the most practical place for the Layer-4 load balancer function in my architecture?
  • Why are network gateways great places for Layer-4 load balancing functions?
  • What are the options (suitable for Kubernetes)?
  • Practical, cloud-like network gateway with native Kubernetes integration

Linux machine + optionally DPDK / SmartNIC acceleration can make a great network gateway with Layer-4 load balancer and native integration with Kubernetes. Almost any common Linux distribution has the minimum building blocks i.e. Layer-2, Layer-3, Layer-4 network functionality. Good read!

[Read More]
Applying test-driven development to your database

Categories

Tags cloud-and-infrastructure data-and-analytics devops-and-ci-cd testing-and-quality

Test-driven development (TDD) is a popular software development methodology that aims to reduce defects and improve the ease of maintaining code. In this post, you learn how to apply TDD to write queries and expressions with the Fauna Query Language (FQL). By Ron Callahan.

TDD begins with writing a single failing test. For example, if you are implementing a Split() function that accepts a string and a delimiter and returns an array of strings “split” at each occurrence of the delimiter, you would test that Split(“127.0.0.1”, “.”) is equal to [“127”, “0”, “0”, “1”]. When you first run your test suite, the test fails, because you have not yet implemented the Split() function.

The tutorial reads about:

  • TDD overview
  • Setting up your environment
  • Configuring Jest
  • Testing partial FQL expressions
  • Preparing your test harness
  • Create a single failing test
  • Implementation

To test your knowledge, try implementing tests for the remaining two specifications. Once you have those tests in place and passing, try to refactor the implementation of Split(). Notice how TDD allows you to safely refactor your code without introducing regressions. Interesting!

[Read More]

An introduction to the Azure DevOps toolset

Categories

Tags cloud-and-infrastructure devops-and-ci-cd

In this post, we start to delve into DevOps toolsets, specifically Microsoft Azure DevOps Services. This is the third in a series of blog posts about DevOps. By Ron Callahan.

Just some of the benefits of a DevOps toolset include the standardization and automation of development processes, improved collaboration within and among the teams, consolidated code repositories, work-item tracking, automated testing, and release pipelines.

Tools (or one person) will not automatically transform an IT department into a DevOps shop, but a department that has adopted the culture and organization to follow DevOps practices WILL benefit from a suite of DevOps tools as they mature.

The article then deals with:

  • Azure Boards
  • Azure Pipelines
  • Azure Repositories
  • Azure Test Plans
  • Azure Artifacts

Faster development cycles allow businesses to push out new features faster, allowing them to be more agile in responding to their competition and to new requests from customers. Furthermore, a tightly integrated CI/CD platform means less downtime – and less downtime equals more revenue! Good read!

[Read More]

Cloud egress charges: How to prevent these creeping costs

Categories

Tags leadership-and-career cloud-and-infrastructure devops-and-ci-cd

One of the advantages of using the cloud is the ability to scale rapidly. On-demand scalability can eliminate the need to overbuy capacity that is only required for peak times. By factioninc.com.

Data egress is when data leaves a network and goes to an external location. If you’re using the cloud, data egress occurs whenever your applications write data out to your network or whenever you repatriate data back to your on-premises environment. While cloud providers usually do not charge to transfer data into the cloud (“ingress”), they do charge for data egress in most situations. Another charge related to data egress fees are data transfer fees, which may be assessed when moving data between regions or availability zones within the same cloud provider.

The article pays attention to:

  • What is data egress?
  • Egress fees can hinder innovation
  • How are egress fees calculated?
  • Best practices to reduce or eliminate egress fees

Data egress fees can vary considerably. Each cloud has its own egress fee structure. Use clouds with higher egress fees for only the workloads that require the capabilities of that specific cloud. workloads that demand it. When services are comparable, always choose the less expensive option. While an older article it is a good read!

[Read More]

Building Real-Time ETL Pipelines with Apache Kafka

Categories

Tags data-and-analytics

Whether you’re a data engineer, a data scientist, a software developer, or someone else working in the field of software and data - it’s very likely that you have implemented an ETL pipeline before. By Stefan Sprenger.

ETL stands for Extract, Transform, and Load. These three steps are applied to move data from one datastore to another one. First, data are extracted from a data source. Second, data are transformed in preparation for the data sink. Third, data are loaded into a data sink. Examples are moving data from a transactional database system to a data warehouse or syncing a cloud storage with an API.

The article content is split into:

  • What are real-time ETL pipelines?
  • What are the benefits of real-time ETL pipelines?
  • How to implement real-time ETL with Apache Kafka

The open-source community provides most essentials for getting up and running. You can use open-source Kafka Connect connectors, like Debezium, for integrating Kafka with external systems, implement transformations in Kafka Streams, or even implement operations spanning multiple rows, such as joins or aggregations, with Kafka. Good read!

[Read More]

Plain English description of monads without Haskell code

Categories

Tags software-engineering architecture-and-apis leadership-and-career

Monads are notorious in the programming world for their use in the Haskell programming language and for being hard to grasp. There’s even a joke that writing a “monad tutorial” is a rite of passage for new Haskellers, and been described as pointless. By Chris Done.

One of the Haskell designers3 in the 90s just came up with a class/interface that worked for all of these. As he was into category theory, he “monad”. The types also sort of match the theory if you squint hard enough.

You can re-use your intuition from existing common place chaining of things in other popular languages:

  • Async chains (JS)
  • Parser combinator chains (Rust, JS)
  • Optional or erroneous value chains (TypeScript, Rust)
  • Continuation passing style (you can do this in Lisp and JS)
  • Cartesian products/SQL (C#’s LINQ)

Monad is the name of the class for “and_then”,5 defined in a sensible way, with some laws for how it should behave predictably, and then a bunch of library code works on anything that implements “and_then”. Apart from F# or Haskell (or descendants), no other language embraces the abstraction with syntax so it’s hard to find a good explanation without them. It’s like explaining Lisp macros without using a Lisp, the explanation tends to be awkward and unconvincing.

Haskellers don’t like to throw exceptions, or use mutation, and functions can’t return early, etc. Suddenly Monad and syntactic sugar for it looks pretty attractive to them. Nice one!

[Read More]

How to create your own Google Chrome extension

Categories

Tags miscellaneous frontend-and-mobile product-and-design

If you are a Google Chrome user, you’ve probably used some extensions in the browser. Have you ever wondered how to build one yourself? In this article, I will show you how you can create a Chrome extension from scratch. By Sampurna Chapagain.

The article then will help you understand the following:

  • What is a Chrome Extension?
  • What will our Chrome Extension Look Like?
  • How To Create a Chrome Extension
  • Creating a manifest.json file

A chrome extension is a program that is installed in the Chrome browser that enhances the functionality of the browser. You can build one easily using web technologies like HTML, CSS, and JavaScript. As we discussed earlier, building a Chrome extension is similar to building any web application. The only difference is that the Chrome extension requires a manifest.json file where we keep all the configurations. Good read!

[Read More]

The file system access API with Origin Private File System

Categories

Tags miscellaneous frontend-and-mobile leadership-and-career

It is very common for an application to interact with local files. For exampe, a general workflow is opening a file, making some changes, and saving the file. By Sihui Liu.

For web apps, this might be hard to implement. It is possible to simulate the file operations using IndexedDB API, an HTML input element with the file type, an HTML anchor element with the download attribute, etc, but that would require a good understanding of these standards and careful design for a good user experience. Also, the performance may not be satisfactory for frequent operations and large files.

The article then describes:

  • Origin Private File System
  • Persistence
  • Browser Support
  • API
  • Examples

The API is currently unavailable for Safari windows in Private Browsing mode. For where is it available, its storage lifetime is the same as other persistent storage types like IndexedDB and LocalStorage. The storage policy will conform to the Storage Standard. Safari users can view and delete file system storage for a site via Preferences on macOS or Settings on iOS. Nice one!

[Read More]

OPC UA, MQTT, and Apache Kafka - The Trinity of data streaming in IoT

Categories

Tags data-and-analytics cloud-and-infrastructure

In the IoT world, MQTT and OPC UA have established themselves as open and platform-independent standards for data exchange in Industrial IoT and Industry 4.0 use cases. Data Streaming with Apache Kafka is the data hub for integrating and processing massive volumes of data at any scale in real-time. By Kai Waehner.

Machine data must be transformed and made available across the enterprise as soon as it is generated to extract the most value from the data. As a result, operations can avoid critical failures and increase the effectiveness of their overall plant.

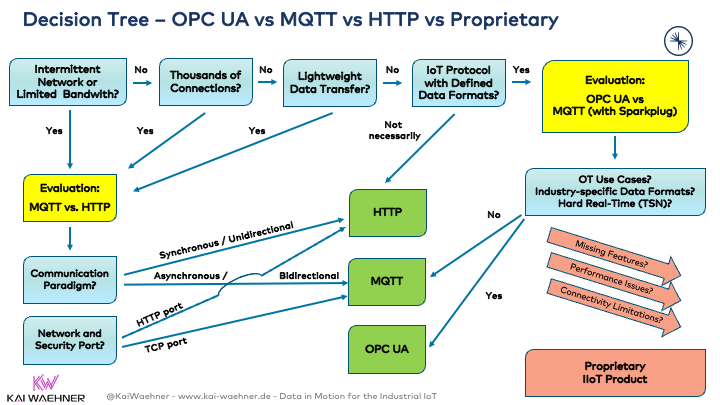
Decision tree for evaluating IoT protocols

Source: https://www.kai-waehner.de/blog/2022/02/11/opc-ua-mqtt-apache-kafka-the-trinity-of-data-streaming-in-industrial-iot/

The article then describes:

  • Kappa architecture for a real-time IoT data hub
  • When to use Kafka vs. MQTT and OPC UA?
  • Meeting the challenges of Industry 4.0 through data streaming and data mesh
  • Separation of concerns in the OT/IT world with domain-driven design and true decoupling
  • How to choose between OPC UA and MQTT with Kafka?
  • Decision tree for evaluating IoT protocols
  • Integration between MQTT / OPC UA and Kafka
  • BMW case study: Manufacturing 4.0 with smart factory and cloud

… and much more. An event-driven data streaming platform is elastic and highly available. It represents an opportunity to increase production facilities’ overall asset effectiveness significantly. With the help of data processing and integration capabilities, data streaming complements machine connectivity via MQTT, OPC UA, HTTP, among others. This allows streams of sensor data to be transported throughout the plant and to the cloud in near real-time. Nice one!

[Read More]

Streaming analytics with Apache Pulsar and Spark structured streaming

Categories

Tags data-and-analytics leadership-and-career cloud-and-infrastructure

Apache Pulsar, a promising new toolkit for distributed messaging and streaming. In this piece we combine two of our favorite pieces of tech: Apache Pulsar and Apache Spark. By Daniel Ciocîrlan.

Apache Pulsar excels at storing event streams and performing lightweight stream computing tasks. It’s a great fit for long term storage of data and can also be used to store results to some downstream applications.

Stream processing is an important requirement in modern data infrastructures. Companies now aim to leverage the power of streaming and real-time analytics in order to provide results faster to their users in order to enhance the user experience and drive business value. Typically, streaming data pipelines require a streaming storage layer like Apache Pulsar or Apache Kafka, and then in order to perform more sophisticated stream processing tasks we need a stream compute engine like Apache Flink or Spark Structured Streaming.

The article main points are:

  • The role of Apache Pulsar in streaming data pipelines
  • Example use case: Real-time user engagement
  • Using the Apache Pulsar/Spark Connector

In this article we discussed the role of Apache Pulsar as a backbone of a modern data infrastructure, the streaming use cases Pulsar can support, and how you can use it along with Spark Structured Streaming to implement some more advanced stream processing use cases by leveraging the Pulsar Spark Connector. We also reviewed a real world use case, demonstrated a sample streaming data pipeline, and examined the role of Apache Pulsar and Spark Structured Streaming within the pipeline. Good read!

[Read More]